I BUILD
SYSTEMSthat
LEARN, REASON
& ACT.
Rejecting colorful clichés. Constructing high-throughput multi-agent graphs, sub-second conversational voice bots, and deterministic distributed backends on pure mathematical principles.
AI Systems Your Business Can actually Rely On.
From stateful cyclical multi-agent reasoning graphs to low-latency voice telephony and hardened FastAPI backends, I engineer systems built for deterministic production execution.
Autonomous Multi-Agent Swarms
Stateful cyclical multi-agent graphs that autonomously reason, delegate tasks, execute tools, and self-correct.
Autonomous deep research, code generation loops, and multi-tenant customer copilots.
Enterprise RAG Architectures
Production-grade hybrid vector & BM25 retrieval engines with cross-encoder reranking and strict zero-hallucination grounding.
Complex multi-document analysis, legal/financial Q&A, and high-accuracy compliance assistants.
Real-Time Voice AI Telephony
Ultra-low-latency conversational voice bots featuring sub-second streaming STT, real-time LLM reasoning, and natural voice synthesis.
Inbound/outbound customer support, front-desk receptionists, and live WebRTC meeting copilots.
Scalable AI Microservices
High-concurrency asynchronous backends engineered specifically to orchestrate model inference and streaming tokens under peak traffic.
High-throughput API gateways, model proxying with fallback routing, and distributed task workers.
Prompt Architecture & LLMOps
Optimizing LLMs for domain-specific accuracy through strict schema guarantees, token latency pruning, and quantitative benchmark harnesses.
Deterministic JSON extraction, model distillation, and production regression evaluation.
Self-Healing Workflow Automation
Connecting disparate enterprise systems, CRMs, and databases into autonomous, self-healing event-driven pipelines with dead-letter recovery.
Intelligent document processing, multi-system CRM synchronization, and proactive incident response.
Featured case Studies
Autonomous multi-agent swarms, enterprise RAG engines, and scalable production systems delivering measurable business outcomes.
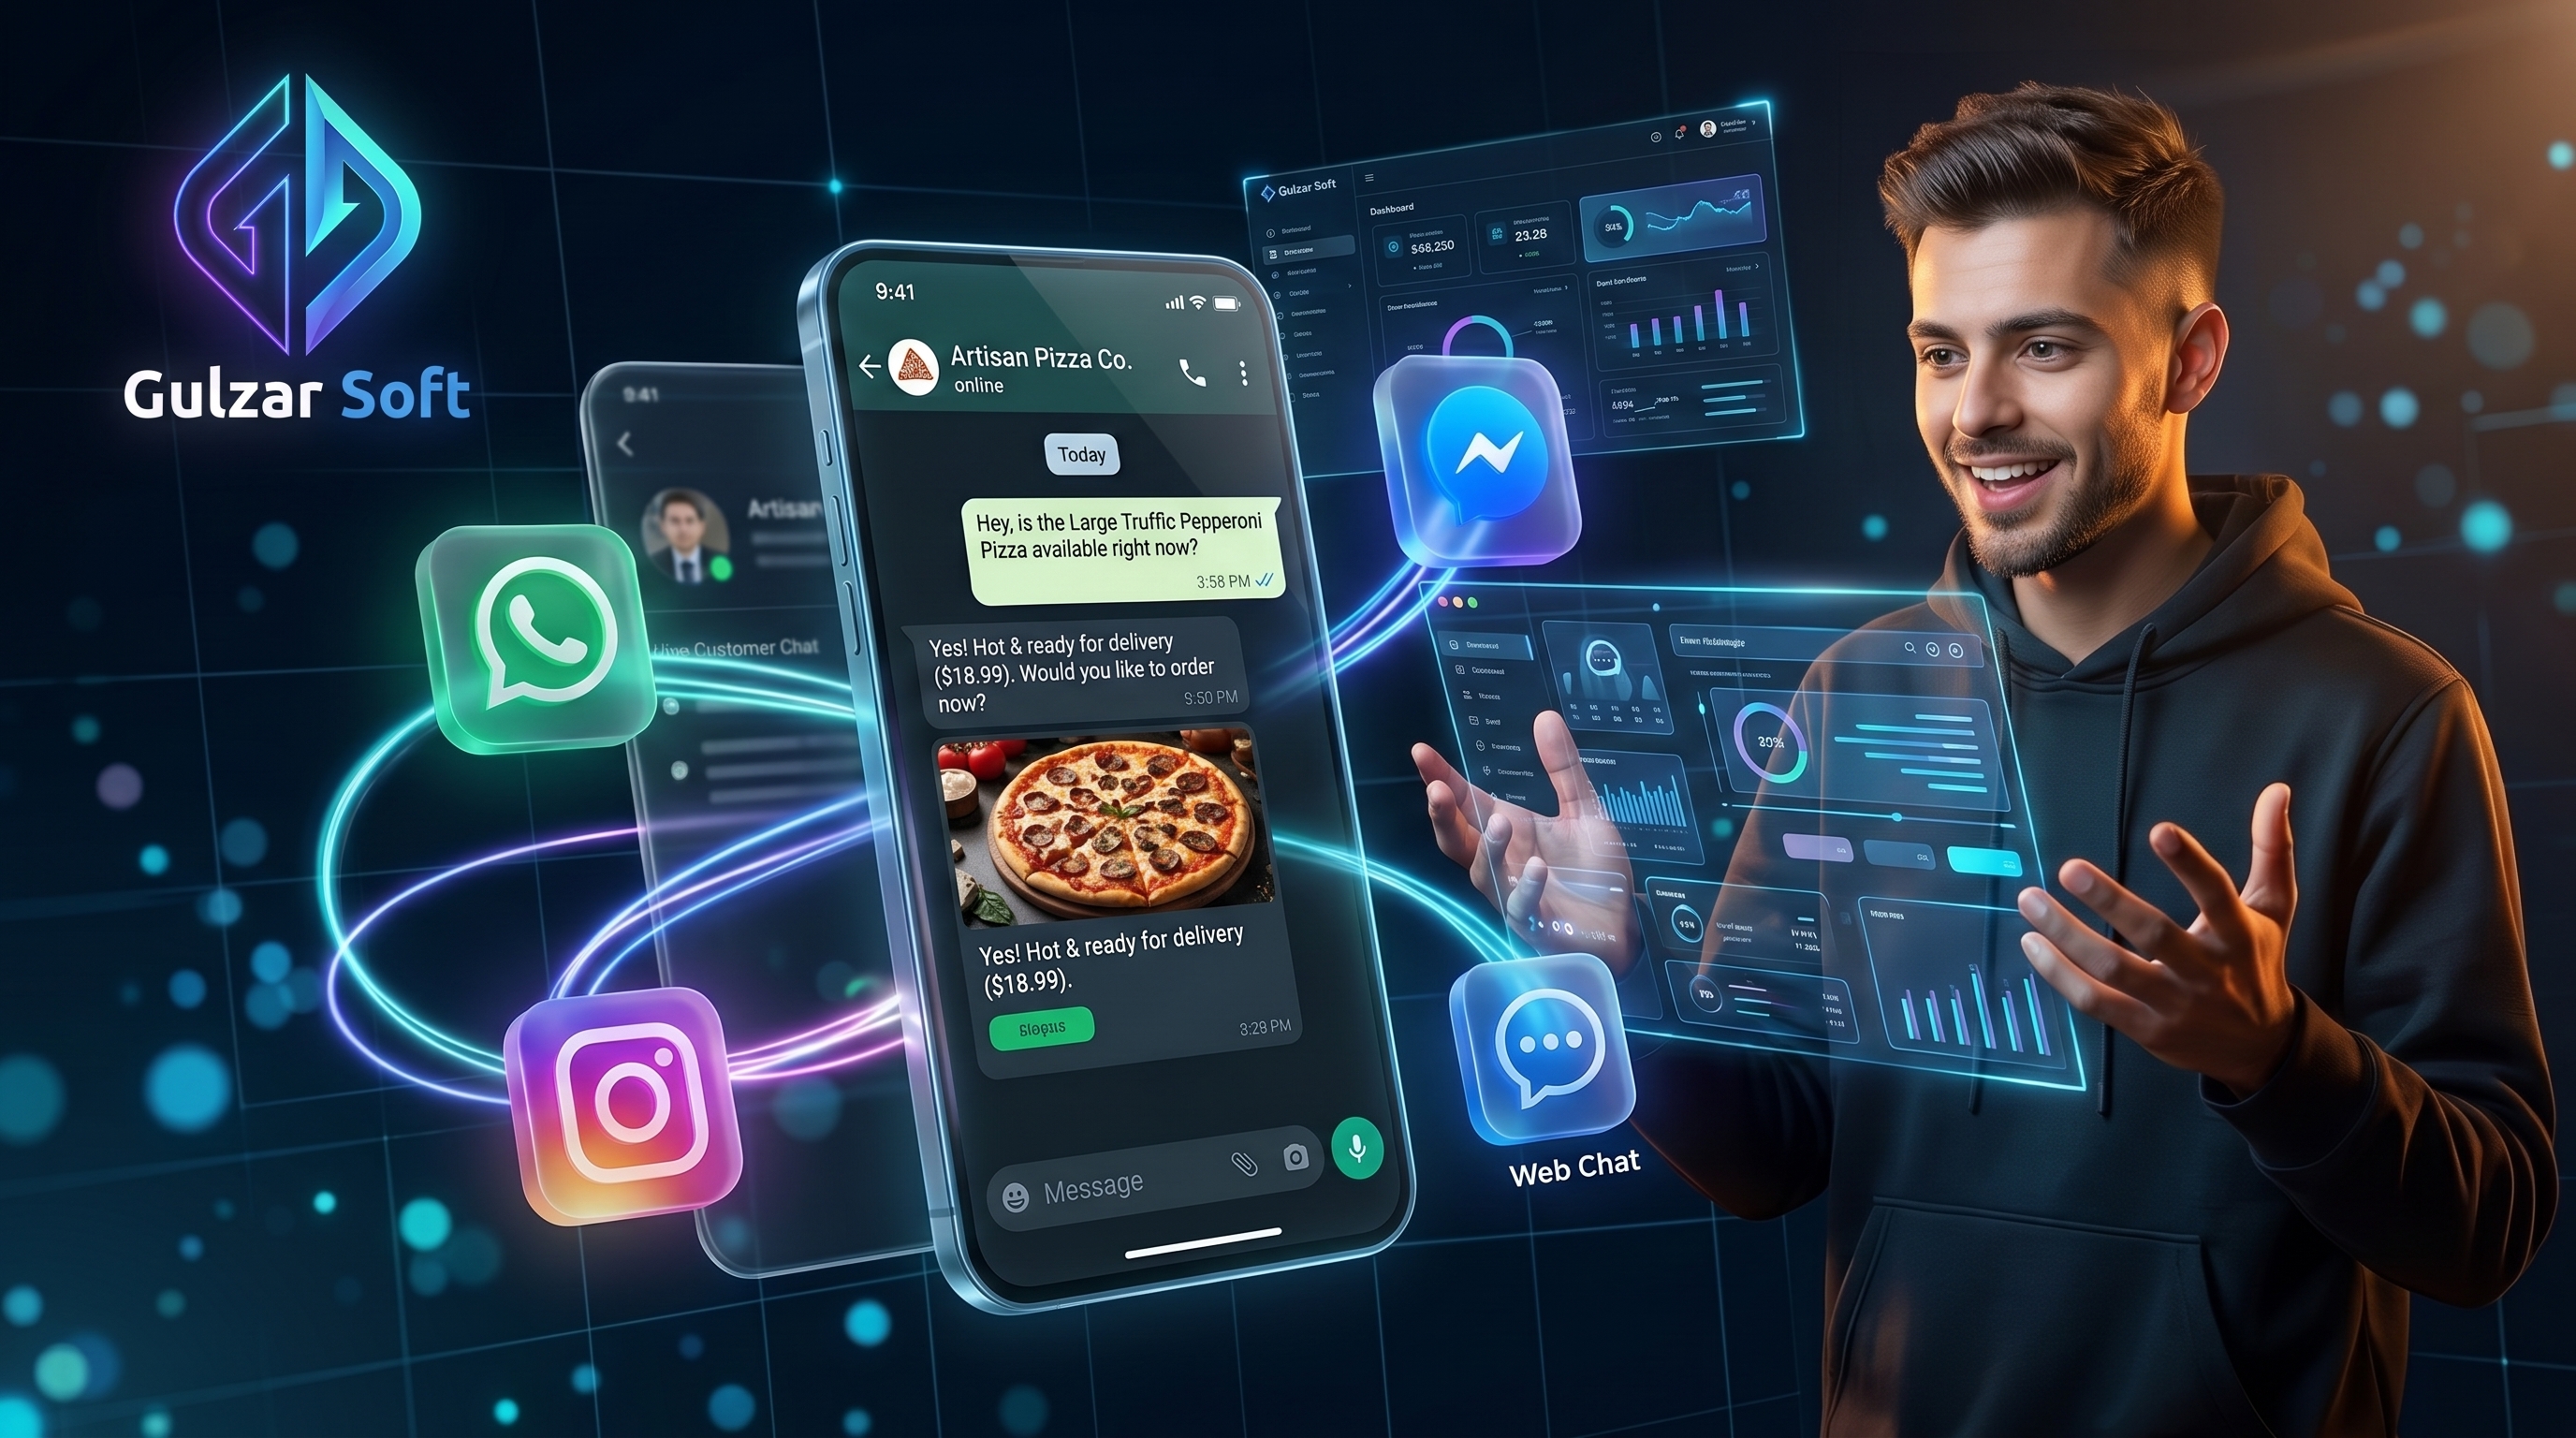
Growmina: Multi-Tenant AI Sales & Support Agent
Growmina is an enterprise-grade conversational AI platform that turns social messaging channels—WhatsApp, Instagram, Facebook Messenger, and Web Chat—into 24/7 autonomous sales and customer support engines. Instead of losing potential buyers to delayed replies or frustrating button-based bots, Growmina equips brands with proactive, human-like shopping assistants that converse naturally, recommend products, and answer policy queries instantly. Key product capabilities include: • Omnichannel Conversational Selling: Meets customers where they already shop, guiding them from casual inquiry to product selection directly inside WhatsApp, Instagram DMs, and Messenger. • Reliable, Grounded Knowledge: Connects directly to each brand's proprietary product catalogs, size charts, and FAQs to deliver accurate pricing and stock details with zero made-up answers. • True Multi-Tenant SaaS: Enables multiple businesses to independently manage their isolated product knowledge, assistant personas, and social channels under a single secure, white-label platform.
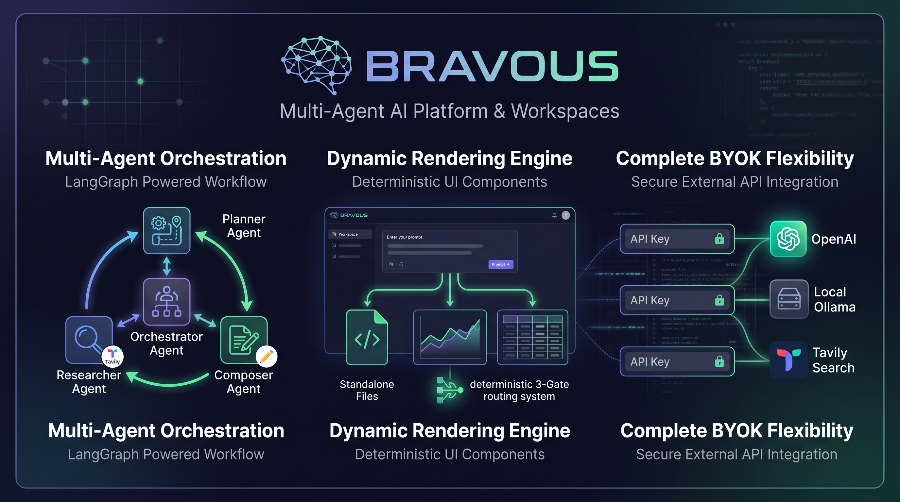
Bravous: Multi-Agent AI Workspace
Bravous is a sophisticated multi-agent AI platform that fully clones and extends Claude's 'Projects' feature. It provides power users with isolated AI workspaces tailored to specific domains, ensuring strict data separation and focused context. Key technical achievements include: • Multi-Agent Orchestration: Utilizes a LangGraph-powered state graph with specialized agents for planning, researching, and composing. • Dynamic Rendering Engine: A deterministic 3-Gate routing system that outputs standalone files or rich inline UI components (e.g., charts, grids) based on data shape. • Complete BYOK Flexibility: Users can securely integrate their own API keys for OpenAI, local Ollama models, and Tavily Search.
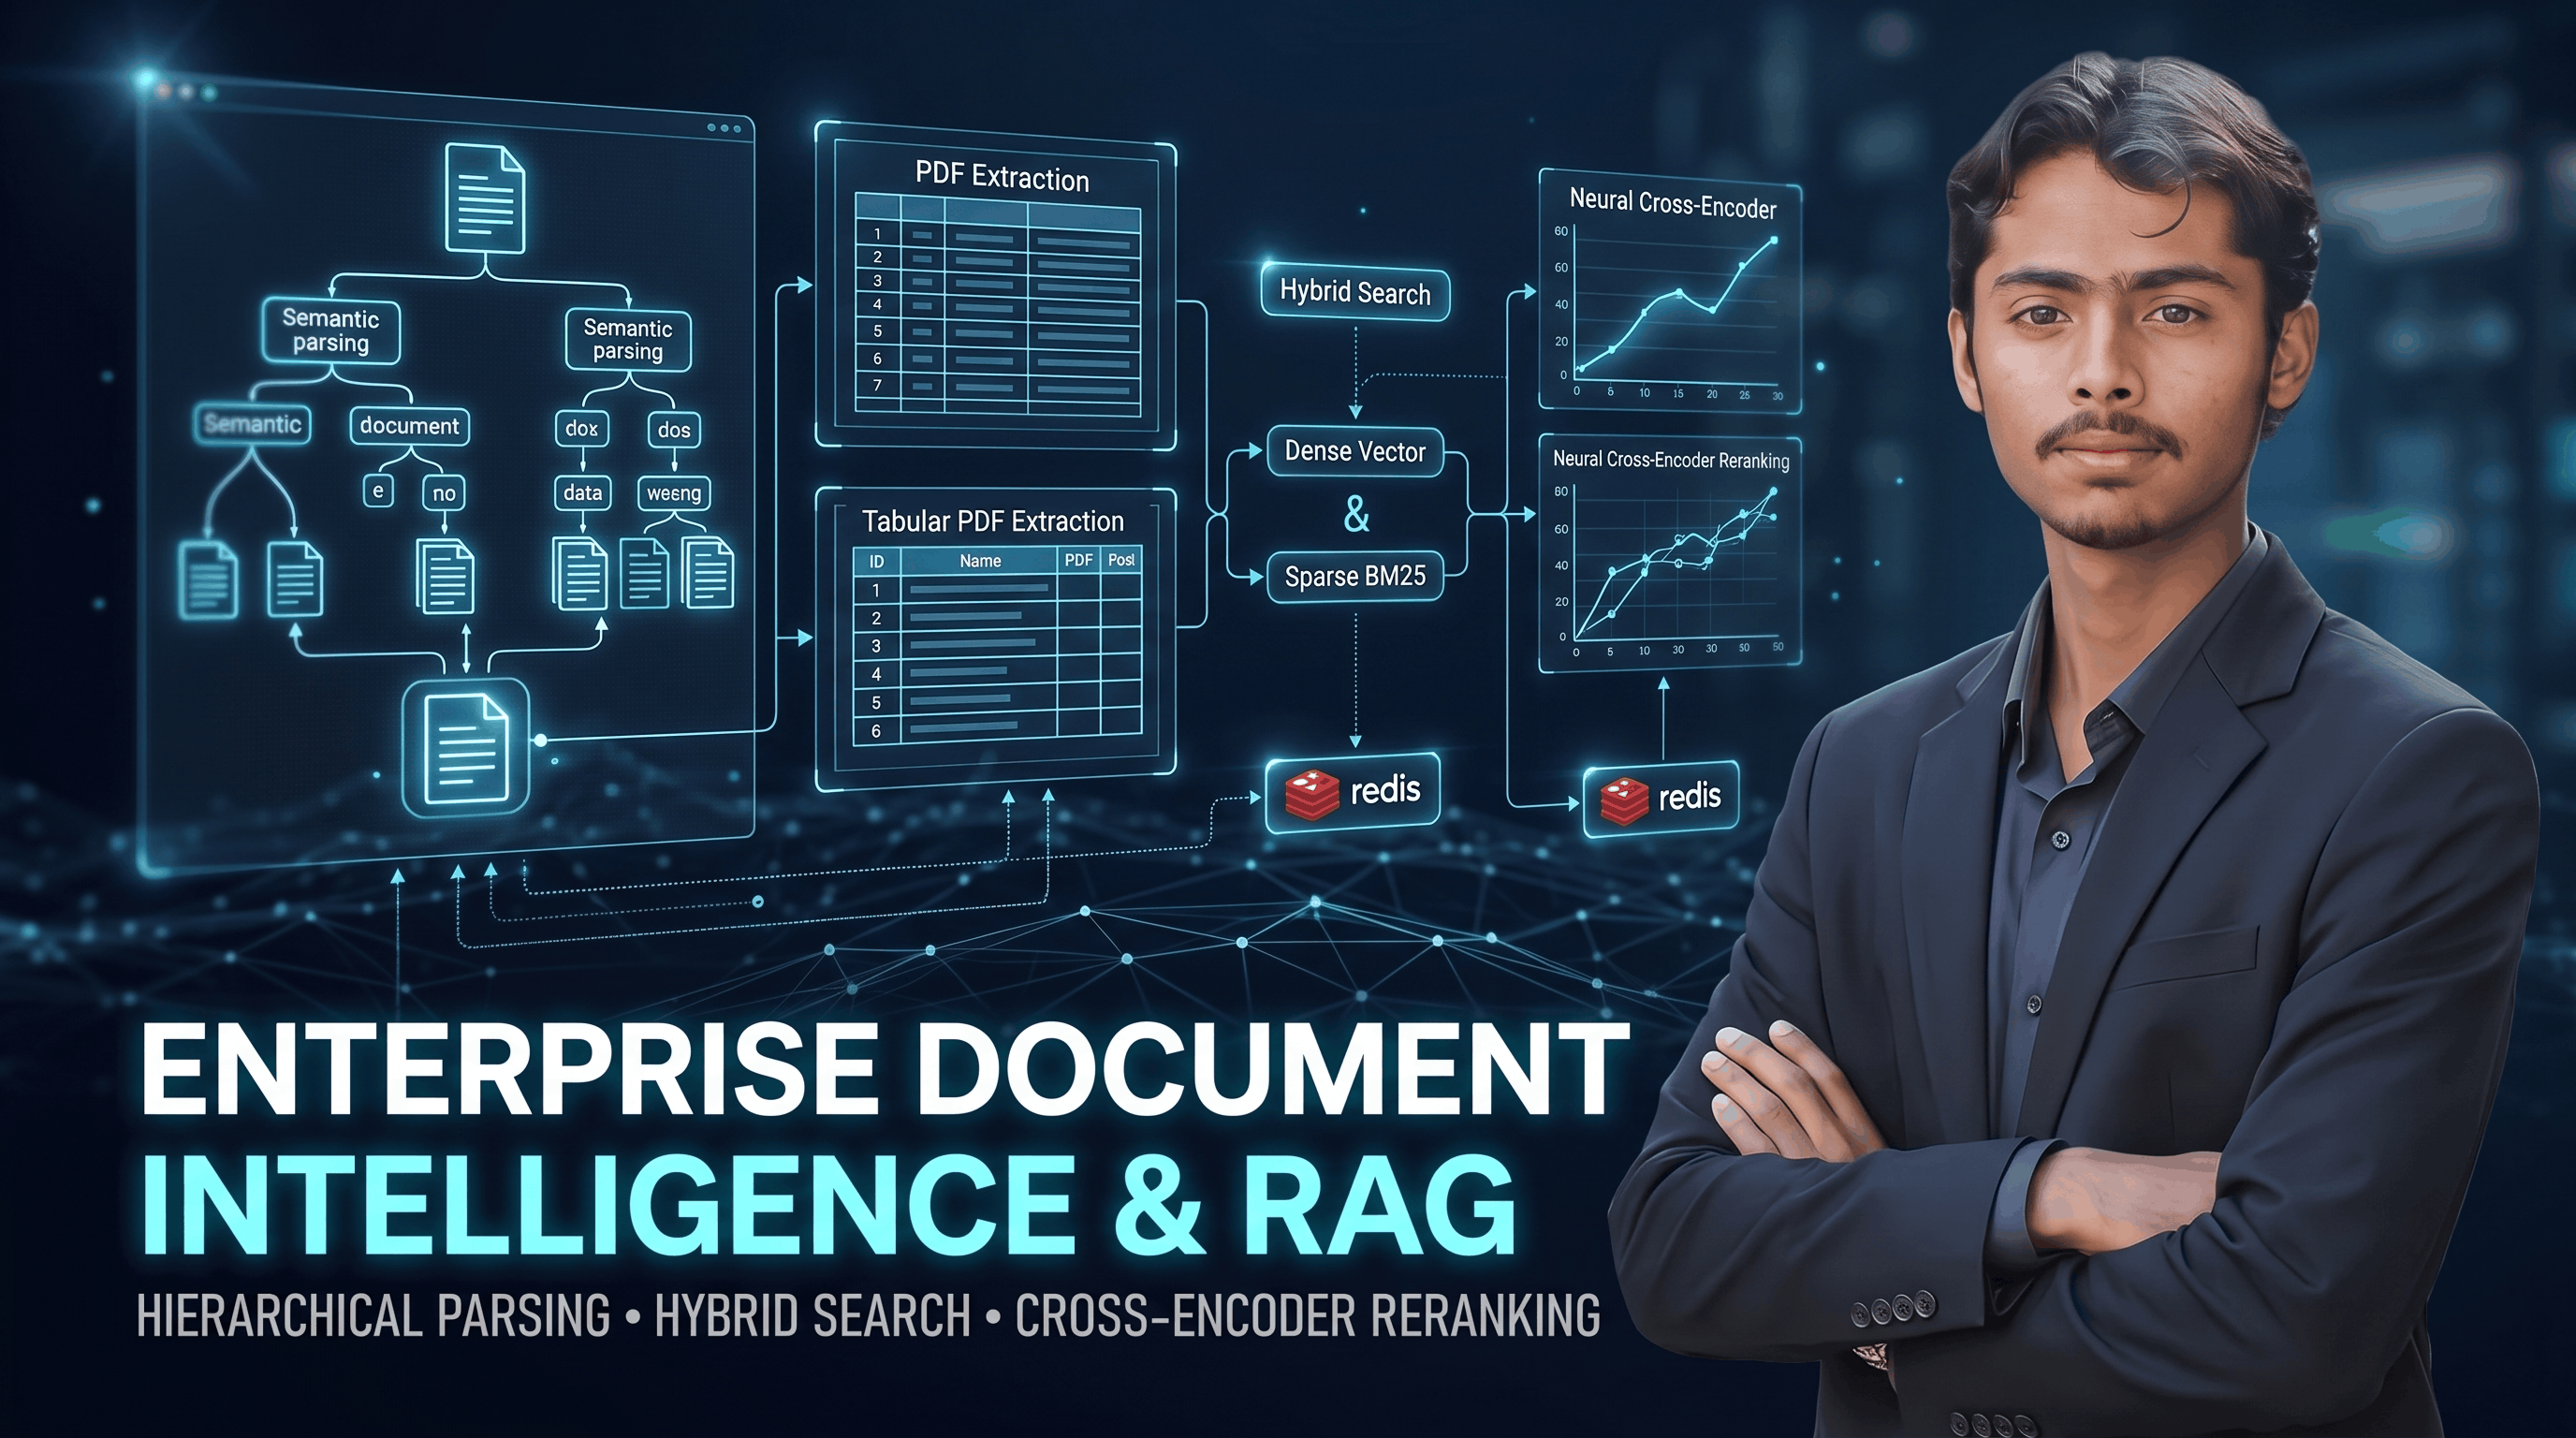
Document Intelligence & Hybrid RAG Engine
Designed and engineered an enterprise-grade Document Intelligence and Retrieval-Augmented Generation (RAG) system tailored for complex compliance and financial documentation. The engine integrates a Docling-powered hierarchical parser that segments documents along semantic H2 heading boundaries, coupled with an incremental hashing syncher that detects content diffs to re-index only modified sections instead of re-embedding entire files. To handle complex reporting documentation, the system extracts tabular structures from native and OCR-scanned PDFs and enriches each table chunk with its parent section hierarchy. The retrieval layer combines dense vector embeddings with sparse BM25 keyword search, refines context with cross-encoder reranking, and slashes query latency through multi-tiered Redis caching and automated Ragas/DeepEval benchmark suites.
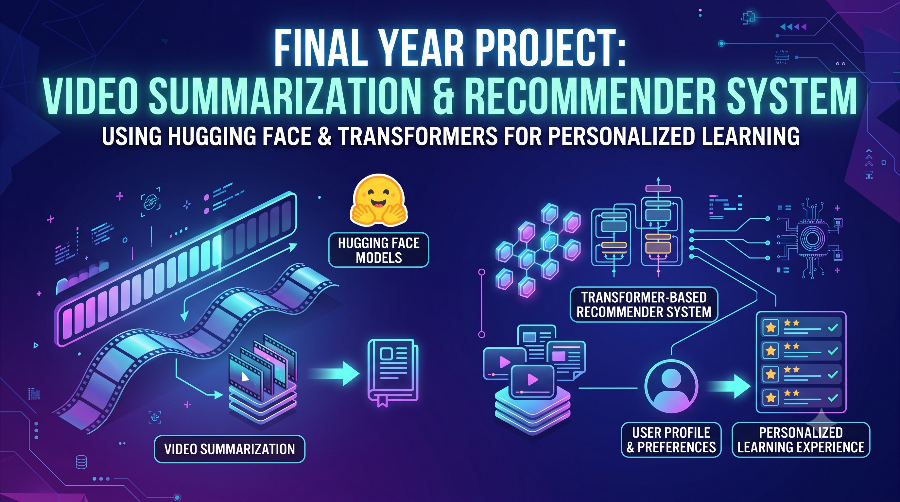
AI-Powered Learning Assistant
Final Year Project: Building a video summarization system using Hugging Face models and implementing a recommender system using Transformer-based architecture for personalized learning experiences.
A Polished Stack Of Tools That ships Real Systems.
Model layer, backend runtime, workflow automation, and cloud deployment—orchestrated with production discipline.
AI + Retrieval
Models, orchestration, retrieval, and evaluation.
Backend + Infra
APIs, state, storage, containers, and deployment.
Automation + Voice
Integrations, real-time calls, and business actions.
Data + ML Core
Statistical modeling, feature engineering, and vision.
Full Stack AI
Model, runtime, workflow & cloud
Full Stack AI
Model, runtime, workflow & cloud
AI + Retrieval
Models, orchestration, retrieval, and evaluation.
Backend + Infra
APIs, state, storage, containers, and deployment.
Automation + Voice
Integrations, real-time calls, and business actions.
Data + ML Core
Statistical modeling, feature engineering, and vision.
How I Engineer & ship AI Systems.
A systematic, evaluation-driven workflow transforming open-ended intelligence into deterministic, production-grade systems with verifiable SLAs.
Deconstruct & Bound
Problem Formulation & Feasibility
Architecture & Topology
Agentic Graphs & State Machines
Deterministic Implementation
Tool-Calling & Schema Enforcement
Evals & Adversarial Gates
Ground-Truth Benchmarks & Safety
Production & Observability
Low-Latency Serving & Telemetry
Deconstruct & Bound
Break complex business domains into deterministic units. Audit data readiness, establish ground-truth baselines, and determine exact boundaries between standard deterministic code and probabilistic models.
Architecture & Topology
Design resilient multi-agent DAGs, state-machine orchestration, and hybrid vector/lexical retrieval strategies. Formulate strict fallback trees to guarantee execution continuity under API failures.
Deterministic Implementation
Implement robust pipelines using strict Pydantic/JSON schemas, sandboxed tool-calling, and real-time streaming backends. Integrate context-aware memory buffers while enforcing strict token boundaries.
Evals & Adversarial Gates
Subject systems to automated LLM-as-a-judge evaluation pipelines, hallucination guards, adversarial prompt injection tests, and regression suites to guarantee deterministic domain fidelity.
Production & Observability
Deploy with semantic caching, distributed rate-limiters, and comprehensive OpenTelemetry tracing. Monitor token burn rates, drift, and user feedback loops for continuous self-correcting refinement.
Engineering Philosophy: “The cheapest, fastest LLM call is the one you never had to make.”
Know what NOT to feed into an LLM
Break complex business domains into deterministic units. Audit data readiness, establish ground-truth baselines, and determine exact boundaries between standard deterministic code and probabilistic models.
Let's Build Something intelligent Together.
Have an applied AI project, multi-agent architecture, or production system to ship? Dispatch your project specifications below or connect across any verified channel.
Tell me
about the
system you
want to build.
Four focused fields. One clear next step. Direct architectural dispatch to Umar's primary terminal with guaranteed evaluation.
Don't hustle to write manually! Describe your raw idea to AI to automate email writing and technical scoping.